Data replication
Pipelines
Learn how Artie pipelines replicate data from your source to your destination in real time.
A pipeline connects a source database to a destination and continuously streams changes. Once created, a pipeline handles initial backfills, schema evolution, and ongoing replication without manual intervention.
Each pipeline consists of:
- Source reader - Connects to your source database and captures changes via CDC. A source reader can be shared across multiple pipelines so your database is only read once.
- Destination connector - Writes changes to a specific destination (e.g. Snowflake, BigQuery, S3).
You can monitor pipeline health, throughput, and latency from the analytics portal.
Writing to multiple destinations
Artie supports reading from a single source and writing to multiple destinations in parallel. For example, you can stream changes to both S3 and Snowflake simultaneously. This is configured by creating multiple pipelines that share the same source reader, so your source database is only read once regardless of how many destinations you have.
This feature is currently available through Terraform.
To set it up, create an artie_source_reader resource and reference it across multiple artie_pipeline resources. Follow Write to multiple destinations for a Terraform example that converts an existing pipeline into this configuration.
Pausing and resuming
You can pause a pipeline from its overview page or from the pipeline list. Pausing doesn’t stop a backfill that’s running. To stop one, use Cancel backfill on the pipeline page. Artie offers two pause modes:
- Pause delivery only - Artie stops writing to the destination but keeps capturing changes from the source for up to 14 days. The pipeline shows Delivery paused. Resume within that window and Artie applies the held changes in order, with no backfill needed.
- Pause pipeline - Artie stops reading from the source and writing to the destination. The pipeline shows Paused. This can cause data to be missed, so you may need to backfill when you resume. On PostgreSQL, the replication slot stays and WAL keeps growing on your database until you resume. For a long pause, you can drop the slot. Artie creates a new slot when you resume, but it misses changes made while paused, so you’ll need to backfill every table.
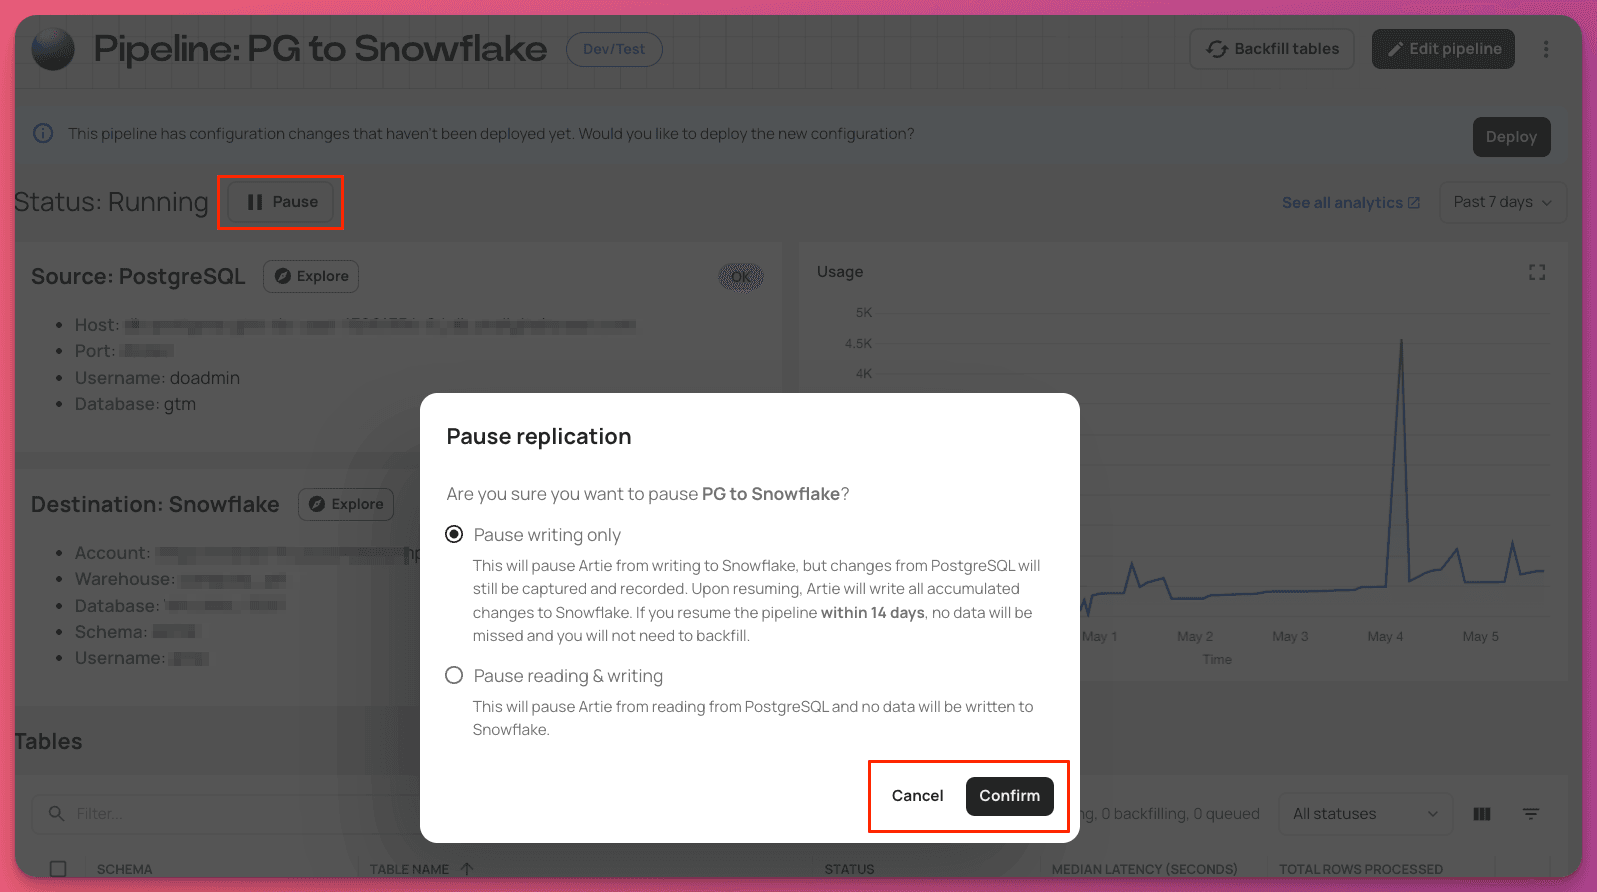
You can also change individual tables. Open the pipeline, click Edit pipeline, go to the Tables tab, and set the table’s Status:
- Pause delivery keeps reading the table but holds its changes for up to 14 days before writing them to the destination. The table shows Delivery paused.
- Stop stops reading the table and writing it to the destination. The table shows Stopped.
- Stream reads and writes the table again. The table shows Streaming.
To change several tables at once, select them and use Edit selected tables.
Message compression
Message compression reduces the number of rows silently skipped due to Kafka’s message size limit by compressing the entire Kafka message value before the size check runs.
Without compression, Artie measures the raw (uncompressed) byte size of each message and drops any that exceed the per-message limit (default 2 MB, can be raised up to 15 MB). A large JSON column can push a row over that limit even when the actual information is modest. With message compression enabled, Artie compresses the value first, measures the compressed size, and only skips the row if the compressed payload still exceeds the limit, which is far less common. To get notified when rows are skipped, subscribe a webhook to the row.skipped event.
Limitations
- Mutually exclusive with column compression. Message compression and column compression cannot both be active on the same pipeline. Enabling one requires the other to be off.
Enabling message compression
- In the dashboard, open your pipeline and go to Edit → Source tab.
- Toggle Message compression on.
- Save the pipeline.
Automatically add new tables
Artie can add eligible new source tables to a running pipeline. In your destination’s Advanced settings, turn on Auto-replicate new tables for regular replication, Auto-enable history mode for new tables for history mode, or both.
By default, Artie checks for new tables every weekday at 6 AM Pacific Time, and company admins can change the schedule in Company settings. You can also trigger a check from the pipeline overview. Use the new-table filters to skip, or only add, tables whose schema.table names match a regex. Tables that already exist when Artie first checks a source are never auto-added.
For the setting names, history-only behavior, validation, automatic deployment, and history-table baseline behavior, see automatically capture newly created tables.
Disable alert emails
By default, Artie sends outbound email alerts when a pipeline encounters issues such as connection failures, replication errors, or sustained ingestion lag. If a pipeline generates noise you want to suppress, such as a non-critical staging pipeline, you can disable alert emails for that pipeline without affecting any other monitoring.
To enable this setting:
- Go to the pipeline editor.
- Click on the Destination tab.
- Click on the Advanced settings tab.
- Enable Disable alert emails.