Data replication
Backfills
Artie runs CDC and backfills in parallel without data conflicts. Database changes are enqueued in Kafka as the backfill is running and applied after backfill completes.
How it works
This is how Artie handles backfills Backfills ensure that all your historical data is copied to your destination. for each table:
A table's backfill and CDC
Both start together. Changes wait in Kafka until the last batch lands.
Artie scans the full table in batches and writes them directly to the destination. It can read from a read replica to keep load off your primary database.
How to kick off a backfill
By default, when you onboard a new table, Artie will kick off a backfill to copy all the historical data to your destination.
To run an ad hoc backfill:
- Open the pipeline’s overview page.
- Open the More options menu and choose Backfill tables… (or Backfill history tables… for history tables).
- Pick the tables. If your destination supports it, choose what happens to the destination tables, then confirm.
Walkthrough
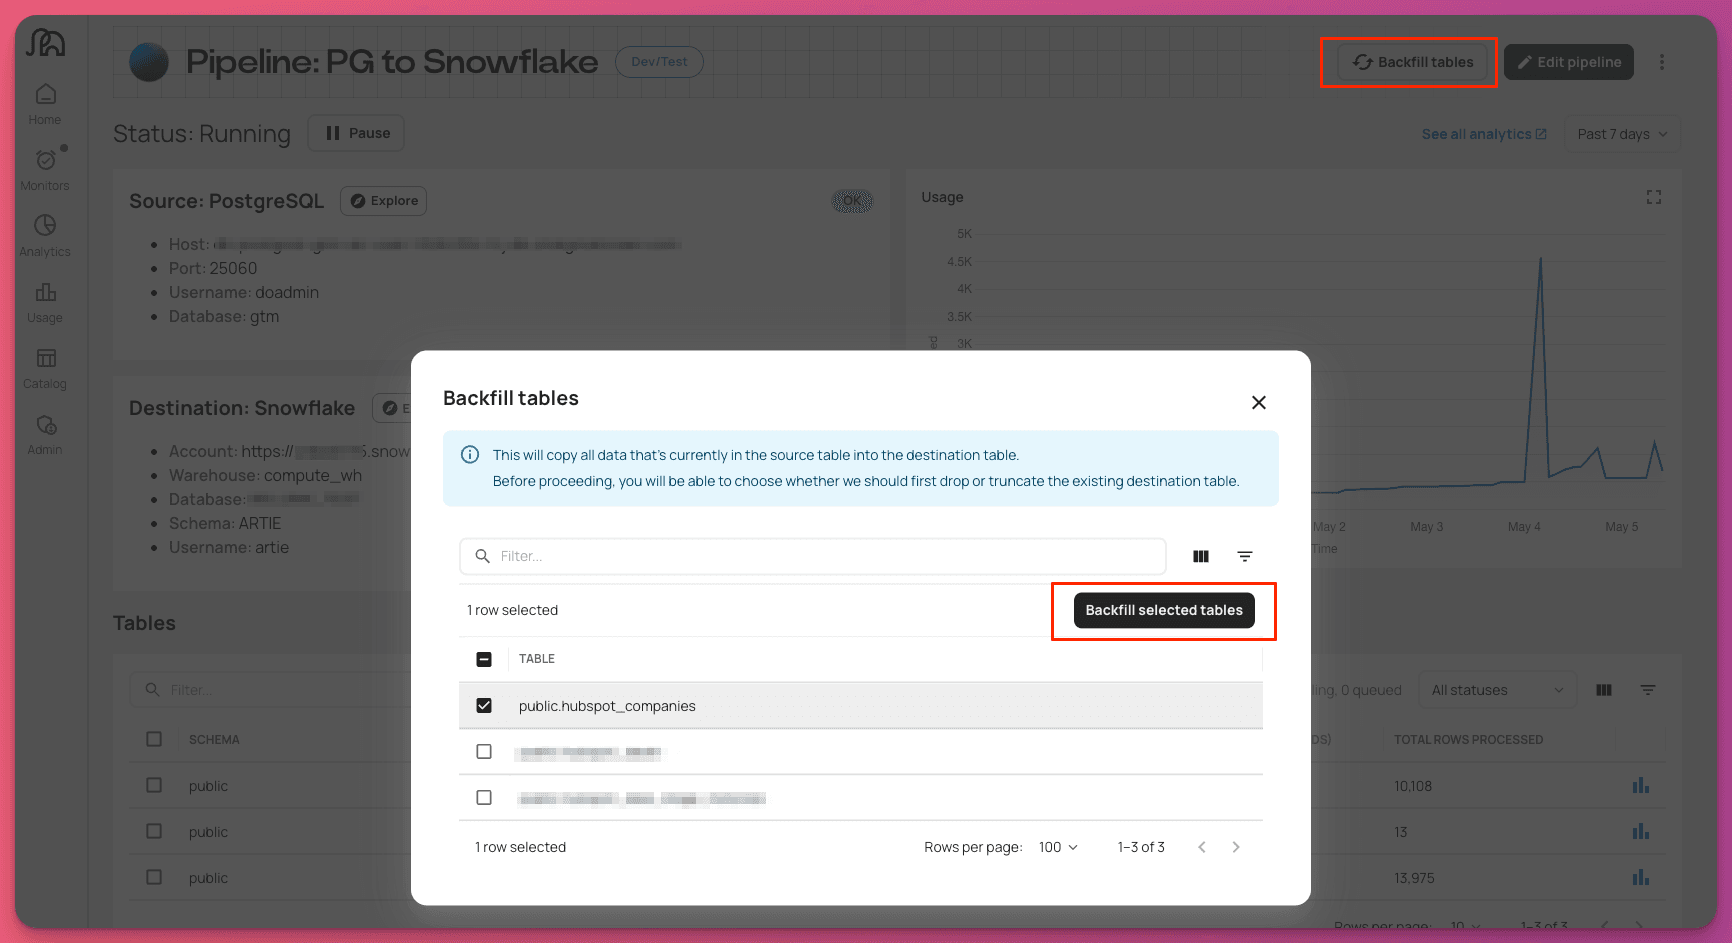
Subsequently, canceling a backfill can be done from the Pipeline overview page.
Destination table behavior
When triggering an ad-hoc backfill, you choose what happens to the destination table before the backfill begins:
Recommended. Artie replaces matching rows and leaves the rest. Rows deleted at the source stay in your destination.
Empties the destination table, keeping its schema, indexes, and grants, then reloads it. Queries see partial data until the backfill finishes.
Recreates the table from the source, including its schema. Use this when the schema changed.
Loads the backfill into a new table and swaps it with the destination table when it finishes, so queries never see the table empty or partially loaded. Snowflake and Databricks only, in early access. See Rebuild and swap backfills.
Advanced settings
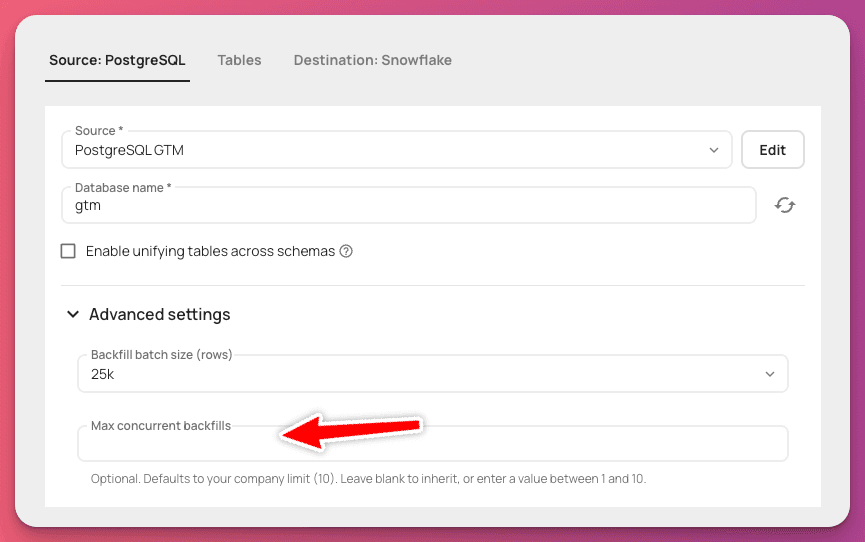
Open your pipeline, click Edit pipeline, and go to the Source tab:
- Backfill settings sets how hard this pipeline’s backfills read from your database. Standard puts a light load on the database and is safe for live traffic. Performance is faster but adds more load, so it works best on a read replica. Open Advanced tuning to see the read method, parallelism, chunk size, and batch size. Standard locks everything except batch size.
- Advanced settings > Max concurrent backfills sets how many tables backfill at once. It defaults to your workspace limit.
To parallelize a single table’s backfill, see table optimizations.
How are backfills ordered?
In FIFO order FIFO (first-in, first-out), tables are backfilled in the order they were added, up to the concurrency limit.
What happens to CDC changes during a backfill?
Our process continues to capture all changes to Kafka in the background. Once backfill completes:
- We switch to CDC stream
- We apply queued changes in order
- The table transitions to fully streaming state
This guarantees consistency and prevents stale data overwrites.