
Iceberg Support Using S3 Tables
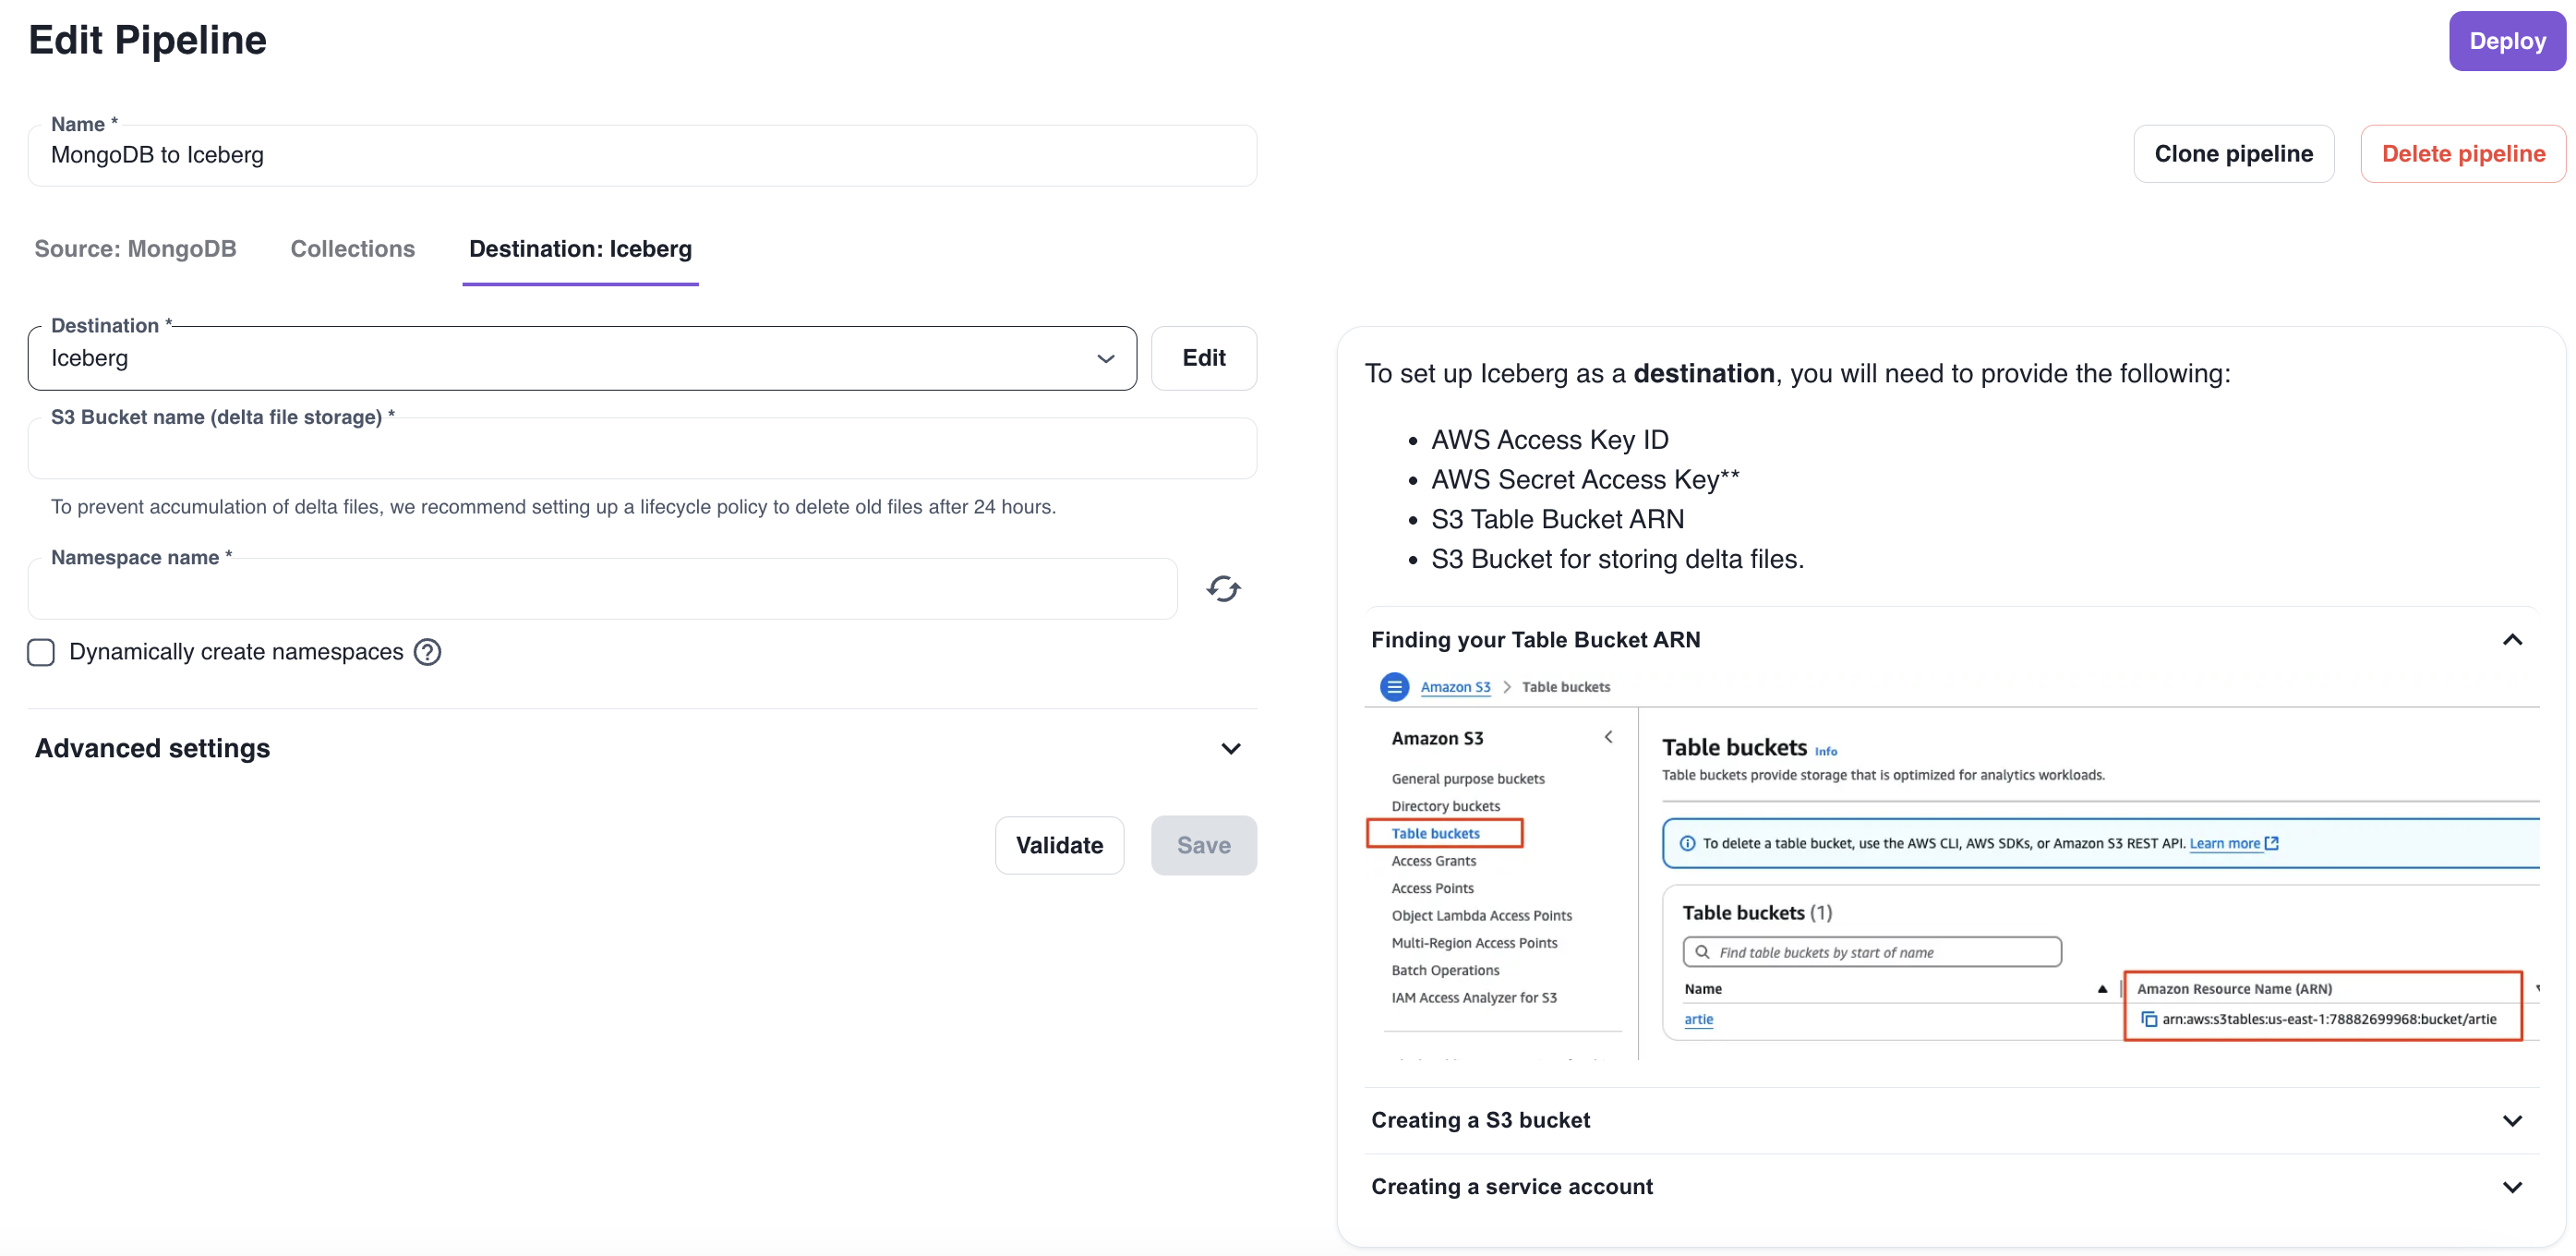
Stream data into Apache Iceberg tables on S3 using S3 Tables, with a managed catalog, compaction, and snapshot management.
This launch adds something big: support for Apache Iceberg using S3 Tables.
Artie customers can now:
- Stream high-volume datasets into Iceberg-backed tables stored on S3
- Use S3 Tables’ fully managed catalog, compaction, and snapshot management
- Query efficiently with Spark SQL (via EMR + Apache Livy) without wrestling with cluster glue
- Get up to 3x faster query performance thanks to automatic background compaction
Why is Iceberg a big deal? Because it solves what’s frustrating and limiting about traditional S3-based data lakes. Hive tables are rigid and brittle, with no snapshotting or time travel. Delta Lake is powerful but tied to the Databricks ecosystem. Plain S3 file storage? No metadata layer, no transactions, no query optimizations.
Instead, Iceberg gives you a fully open, cloud-native table format with smooth schema evolution, hidden partitions, snapshot isolation, and time-travel queries – all with broad engine support (Spark, Trino, Flink, Presto, Hive).
We’re excited about this because it means Artie customers can confidently move massive data volumes without needing to hand-build the plumbing – Iceberg and S3 Tables handle schema changes, partitioning, compaction, and snapshot management behind the scenes, so the system scales cleanly without brittle, custom workflows.
📚 Want to set up Iceberg-backed pipelines? Docs to get started: https://artie.com/docs/destinations/iceberg/s3tables